Task alone
The model has to fill in the gaps.
USER TASK
Add a new API endpoint for this project.
The request leaves project-specific architecture and earlier lessons unstated. The agent may need additional investigation or clarification.
The big picture
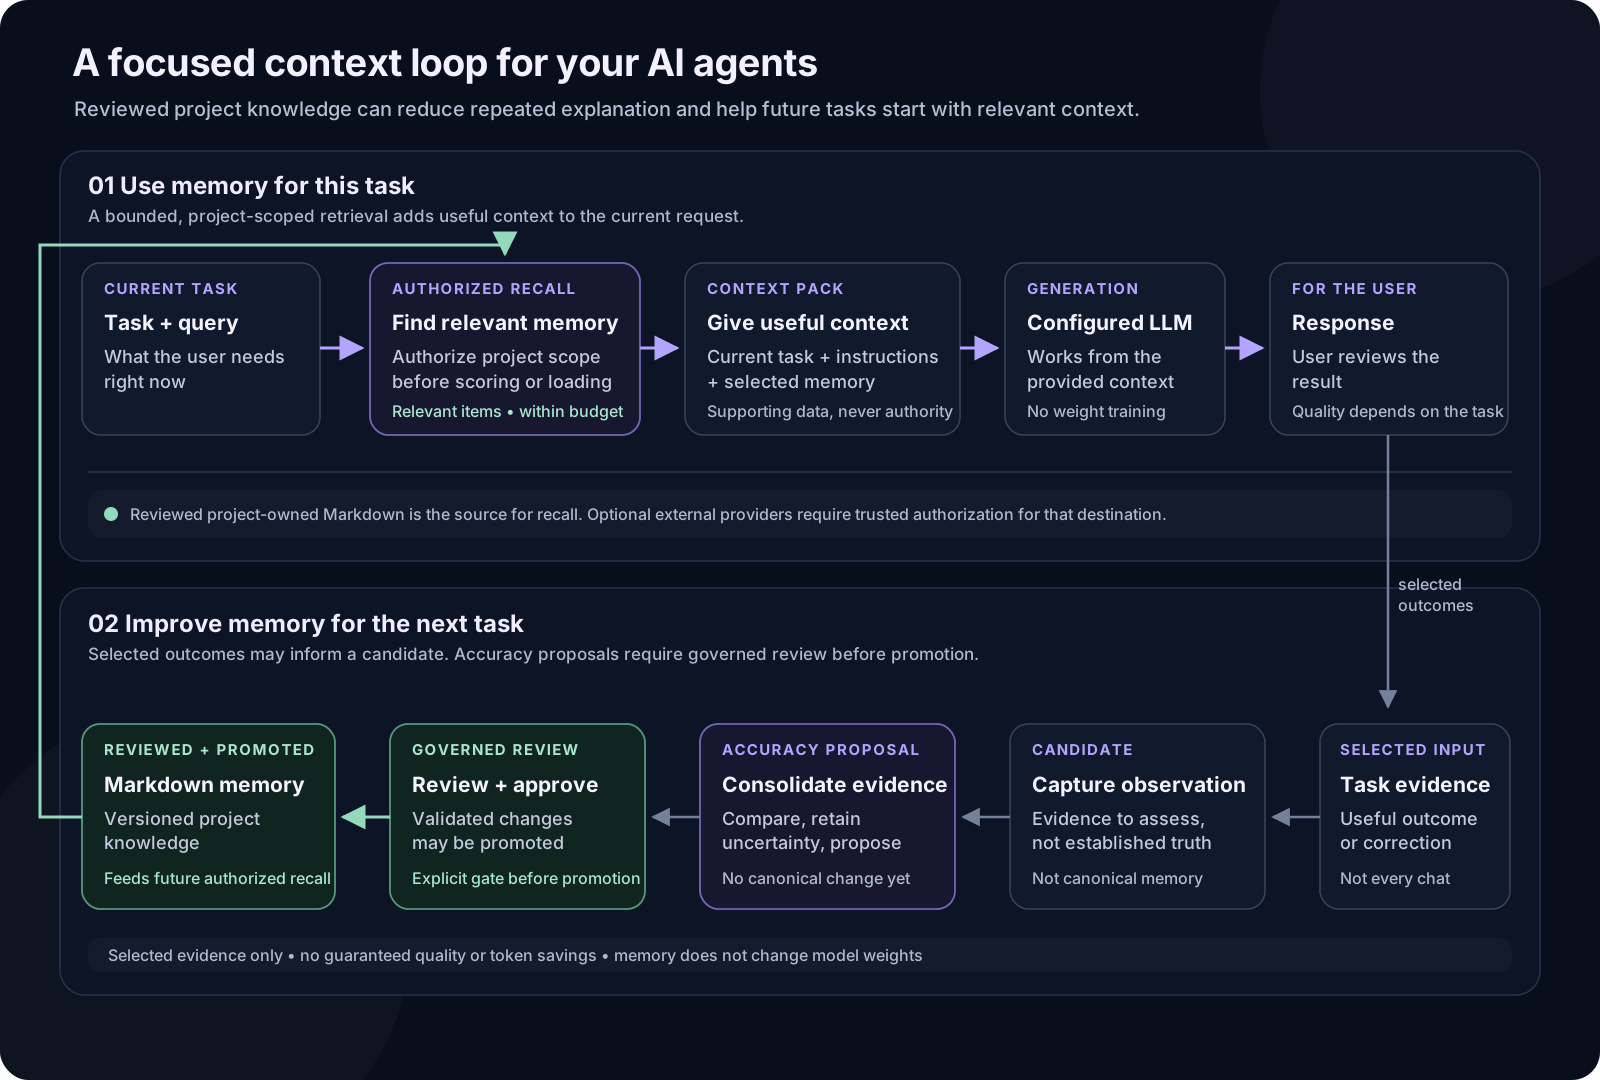
Memora brings relevant project knowledge into an AI agent’s current context. Reviewed decisions and lessons can help the model work with your project’s specifics, while a bounded memory pack can replace repeated history.
The improvement happens in the input context. Memory does not train or change the model’s weights.
01 / Two connected loops
On a small screen, scroll the diagram horizontally or open the full-size vector image. A text walkthrough follows below.
02 / Why the input can improve
A general model may know how to build an endpoint. It may not know why your project chose a particular service boundary. Memory can put that reviewed knowledge beside the current task.
Illustrative project example · not a captured customer conversation or measured outcome
Task alone
Add a new API endpoint for this project.
The request leaves project-specific architecture and earlier lessons unstated. The agent may need additional investigation or clarification.
Task + relevant memory
Add a new API endpoint for this project.
SUPPORTING PROJECT MEMORYRelevant knowledge can reduce repeated explanation and direct investigation toward the right boundaries. It remains supporting evidence, not instruction authority.
Select knowledge related to the task, rather than forwarding everything the project has ever recorded.
Bring prior decisions and verified lessons into a new session without relying on the model to remember an old chat.
Keep evidence, uncertainty, and version history available so people and agents can check what the memory claims.
03 / Where token savings can come from
When a workflow would otherwise resend a long history, a smaller memory pack can reduce input tokens for the next request. The current task and instructions still need room. Savings require the host or workflow to omit the history being replaced; recall does not automatically clear existing chat history.
These are chosen example values, not tokenizer measurements or a Memora benchmark.
| Request | Task + instructions | History or memory | Total input |
|---|---|---|---|
| Resend history | 2,000 | 10,000 history | 12,000 |
| Use selected memory | 2,000 | 1,500 memory | 3,500 |
| Task alone | 2,000 | 0 | 2,000 |
In this example: 10,000 history − 1,500 memory = 8,500 fewer input tokens than resending history.
Compared with the task alone, the memory version adds 1,500 input tokens. The benefit depends on what the retrieved context replaces and whether it helps the task. Token counts also depend on the model’s tokenizer and message format.
Input savings in one request are not the same as a lower total bill. Optional model-backed retrieval, capture or Accuracy processing can add tokens and latency. Output length, provider pricing, caching, and tool calls also affect the result.
A token budget is a limit, not a target to fill or a reason to remove essential evidence. Start from the task, retain important constraints, and compare outcomes on the same tasks and model settings.
04 / Why memory quality matters
The model’s response is not automatically promoted to truth. In the Accuracy proposal workflow, useful experience moves through a separate, governed path.
Record a reusable observation with evidence. Do not ingest every conversation by default.
Assess selected evidence, preserve counter-evidence and uncertainty, and produce a proposal.
Apply the required review, authorization, validation, and publication controls before promotion.
Recall reviewed knowledge when relevant. Check whether it helped, and correct or retire stale knowledge through governed operations.
The ideas behind the approach
OpenAI’s prompt engineering guide explains how relevant context can supply knowledge outside a model’s training data. Anthropic’s context engineering article describes selecting useful information within a limited context budget. These are general principles, not evidence of measured Memora performance or a program affiliation.